What “Autonomous” Actually Means in Enterprise IT (It’s Not a Buzzword)
“Autonomous” has become one of the most frequently used words in technology. It appears in product announcements, strategy documents, conference presentations, and conversations about AI-driven IT operations.
The word is attractive because it suggests a future in which systems can identify problems, make decisions, and resolve issues without waiting for a human to intervene.
But in enterprise IT, autonomy cannot simply mean that software is allowed to act on its own. Real systems operate across sensitive infrastructure, customer-facing applications, identities, data, compliance requirements, and business-critical processes. An unbounded system that makes a fast but incorrect decision can create more risk than the original problem.
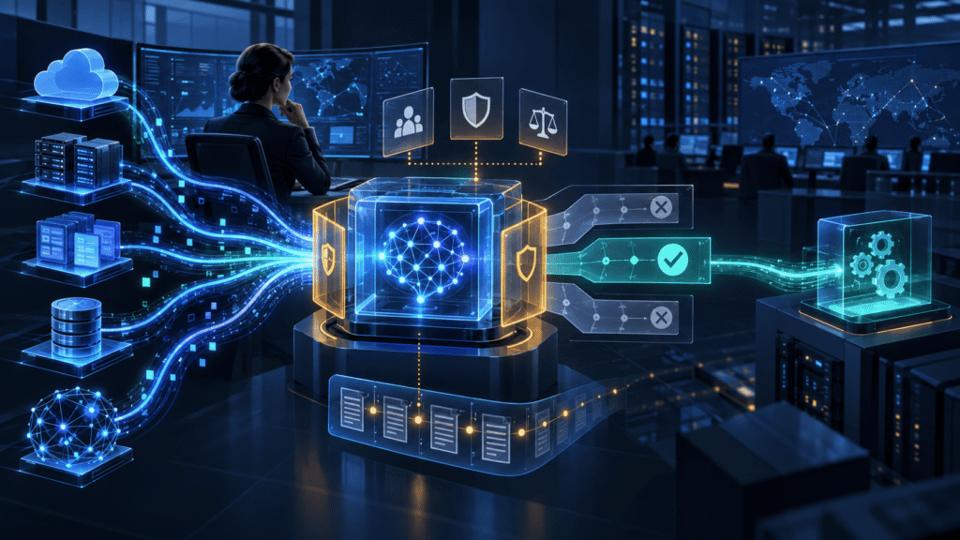
So what does autonomous IT actually mean? It means systems have the authority and intelligence to complete defined operational outcomes within explicit boundaries, while humans retain control over risk, policy, and exceptions.
That definition is less dramatic than “AI runs everything.” It is also much more useful.
Autonomy is not the same as automation
Automation follows instructions. Autonomy manages an outcome.
Traditional automation might execute a script when a threshold is crossed. An autonomous workflow has more responsibility: it interprets the situation, selects from available actions, checks whether the action is appropriate, carries it out, and evaluates the result. As explored in our related piece on why traditional IT automation hits a wall , the difference is not that one uses AI and the other does not. The difference is the level of decision-making involved.
How automation and autonomy differ
- Trigger: Traditional automation responds to a predefined event or schedule, while autonomous IT responds to a contextual condition or operational goal.
- Decision: Automation follows a fixed path; autonomy selects among governed options.
- Exceptions: Automation escalates or fails when conditions change; autonomy adapts within defined limits.
- Action: Automation executes a known step; autonomy plans and executes a bounded response.
- Feedback: Automation is often limited to success or failure; autonomy evaluates the outcome and updates its next decision.
- Human role: With automation, people maintain rules and handle exceptions; with autonomy, people set policy, approve risk boundaries, and handle escalation.
Autonomy builds on automation. It does not make automation obsolete.
The five dimensions of autonomous IT
The term becomes clearer when it is broken into practical capabilities.
1. Perception
An autonomous system needs reliable awareness of its environment. It may consume metrics, logs, traces, tickets, change records, security events, configuration data, and business-impact signals. Perception is not just collecting more data. It is identifying which data is relevant to the outcome the system is responsible for.
2. Interpretation
The system must turn signals into an operating picture. It may correlate alerts, identify recent changes, compare current behavior with historical patterns, and distinguish symptoms from likely causes. This is where context matters. A performance change during an approved deployment may require a different response from the same change during an unrelated customer incident.
3. Decision-making
Autonomous IT requires a way to choose what happens next. That decision may be based on policies, confidence, impact, reversibility, resource availability, and the cost of waiting. The system should not only select an action. It should be able to explain the relevant evidence and the constraints that shaped the decision.
4. Execution
The system must be able to carry out approved actions through reliable tools and interfaces. Execution may involve restarting a service, adjusting capacity, routing a request, opening an incident, applying a known configuration, or requesting human approval. The action set should be explicit. A system cannot be safely autonomous if no one knows what it is permitted to change.
5. Learning and recovery
Autonomy is incomplete if the system cannot determine whether its response worked. It should verify the outcome, detect unintended effects, and roll back or escalate when conditions worsen. Learning does not necessarily mean unsupervised self-modification. In an enterprise, it may mean capturing outcomes, improving recommendations, refining thresholds, and updating approved runbooks through controlled processes.
Levels of autonomy in enterprise IT
Not every workflow needs the same level of independence. A useful maturity model includes several levels.
Level 0: Manual operation
People monitor systems, investigate issues, choose actions, and execute changes manually.
Level 1: Assisted operation
Tools surface signals, summarize information, or recommend next steps. A human makes and executes the decision.
Level 2: Approved automation
The system prepares or performs a known action after a human approval step. The workflow remains deterministic, but the handoff is more efficient.
Level 3: Bounded autonomy
The system can choose and execute low-risk, reversible actions within predefined policies. It escalates when confidence, impact, or uncertainty exceeds a threshold.
Level 4: Coordinated autonomy
Multiple autonomous capabilities work together across a service or process, coordinating actions and evaluating dependencies while remaining subject to governance.
Level 5: Broad autonomy
The system manages a wide operational domain with limited routine intervention. This is the most demanding level and should not be treated as the default target for every organization.
Most enterprise value is likely to come from Levels 1 through 3. Organizations do not need to pursue maximum autonomy to benefit from better decision support and bounded execution.
What autonomous IT is not
Clear boundaries prevent the term from becoming empty marketing language. Autonomous IT is not:
- An AI system with unrestricted production access
- A chatbot placed in front of existing dashboards
- A collection of scripts described with a more ambitious label
- A promise that human expertise is no longer needed
- A reason to remove approval, audit, or rollback controls
- A system that changes its own objectives without governance
If a system cannot explain its authority, operating boundaries, escalation rules, and recovery path, it may be automated, but it is not mature autonomous IT.
Where autonomy makes sense first
The best early use cases have clear outcomes, reliable signals, limited action spaces, and reversible changes. Examples include:
- Restarting a failed non-critical process after validating dependencies
- Adjusting capacity within approved limits
- Routing and enriching service requests
- Collecting evidence for incident triage
- Detecting configuration drift and preparing a remediation
- Applying a known workaround for a recurring, well-understood issue
- Creating and updating operational records across connected tools
These workflows still benefit from human review when impact is high or confidence is low. The objective is to reduce repetitive coordination and response effort while preserving control over consequential decisions.
Why governance is part of autonomy
Governance is not an obstacle to autonomous IT. It is what makes autonomy usable in an enterprise. An autonomous capability should have:
- A clearly defined owner
- A documented purpose and success measure
- A limited set of permitted actions
- Identity and access controls
- Confidence and impact thresholds
- Approval requirements for sensitive changes
- Full action and evidence logging
- Rollback or recovery procedures
- Escalation paths for ambiguity and failure
- Regular review as systems and policies evolve
The more authority a system has, the more important it is to know what it did, why it did it, and what happened afterward.
How to measure autonomy responsibly
Counting the number of automated actions is not enough. A workflow that acts frequently but creates rework is not a success. Useful measures include:
- Percentage of cases resolved without unnecessary escalation
- Time from detection to safe remediation
- Accuracy of diagnosis and prioritization
- Rate of successful versus rolled-back actions
- Number of unintended changes
- Human approval time for governed actions
- Recurrence of the original issue
- Operator trust and override rates
- Business or customer impact avoided
These measures connect autonomy to outcomes rather than novelty.
A practical roadmap to autonomous enterprise IT
Organizations can build toward autonomy in deliberate stages.
Define the outcome
Start with a result, not a technology label. For example: reduce time spent triaging a recurring class of incidents while maintaining a clear approval path for production changes.
Map the decision process
Document what people observe, how they interpret it, which options they consider, and what conditions cause escalation. This reveals where context and policy are missing.
Establish action boundaries
Separate reversible, low-risk actions from changes that require approval. Define what the system can inspect, modify, notify, and escalate.
Add evidence and explanation
Make the signals, policies, and prior knowledge behind a recommendation visible. Trust grows when operators can verify the reasoning.
Start in recommendation mode
Let the system propose actions before it executes them. Use this phase to evaluate quality, identify edge cases, and improve the workflow.
Enable bounded execution
Authorize a narrow set of low-risk actions with logging, monitoring, and rollback. Expand only when the results justify it.
What this means for EBlissAI
For EBlissAI, autonomous enterprise IT should mean practical intelligence with accountable execution. The opportunity is to help teams move beyond isolated scripts and reactive dashboards toward systems that understand context, recommend appropriate action, and operate within policies people can see and trust. If your organization is exploring autonomous IT but needs a clear starting point, reach out to EBlissAI to identify the workflows where bounded autonomy can create measurable value.
Conclusion
“Autonomous” should not be used as a shortcut for “AI-powered” or “fully independent.” In enterprise IT, autonomy is the disciplined ability to sense conditions, interpret context, make governed decisions, act within limits, and verify outcomes.
The most valuable autonomous systems will not remove people from operations. They will remove unnecessary waiting, searching, repetition, and coordination, giving people better information and more time for decisions that truly require judgment.
That is what makes autonomous IT more than a buzzword: it is a measurable operating model with clear authority, clear limits, and clear accountability.
Frequently asked questions
What does autonomous IT mean?
Autonomous IT means systems can detect conditions, interpret context, choose among governed actions, execute within defined limits, and verify outcomes. Human teams remain responsible for policy, risk boundaries, and exceptions.
How is autonomous IT different from automation?
Automation follows predefined instructions for repeatable tasks. Autonomous IT manages a defined outcome by interpreting the situation, selecting an appropriate action within policy, and adapting or escalating when conditions fall outside its boundaries.
Does autonomous IT eliminate human oversight?
No. Responsible autonomous IT uses human oversight for governance, high-impact decisions, exceptions, and changes that exceed defined confidence or risk thresholds. Autonomy should expand safe execution, not remove accountability.
What is a good first use case for autonomous enterprise IT?
A good first use case has reliable signals, a clear outcome, a limited action set, and reversible changes. Examples include incident triage, capacity adjustments within approved limits, service-request routing, and known low-risk remediation.
How can companies govern autonomous IT?
Companies can govern autonomous IT with defined ownership, role-based access, action boundaries, approval thresholds, evidence and action logs, rollback procedures, escalation paths, and regular review of performance and risk.